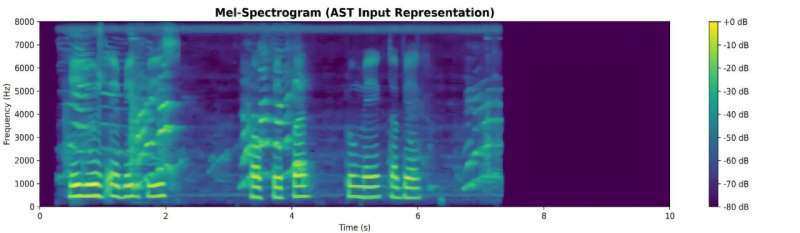
The scientists analyzed 14,759 voice recordings from 461 adults, which were converted into visual spectrograms before being analyzed by an Audio Spectrogram Transformer. The process allows the model to learn complex combinations of acoustic patterns directly from the recordings rather than relying primarily on predefined voice features selected in advance. Using voice only, the sex-stratified models achieved a balanced accuracy of 71.3% for women and 72.4% for men, with area under the receiver operating characteristic curve (AUC) values of 0.788 (78.8%) and 0.779 (77.9%), respectively.